Devpost
Participate in our public hackathons
Devpost for Teams
Access your company's private hackathons
Grow your developer ecosystem and promote your platform
Drive innovation, collaboration, and retention within your organization
By use case
Blog
Insights into hackathon planning and participation
Customer stories
Inspiration from peers and other industry leaders
Planning guides
Best practices for planning online and in-person hackathons
Webinars & events
Upcoming events and on-demand recordings
Help desk
Common questions and support documentation
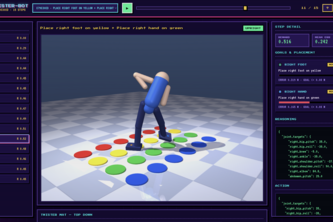
Can AI play Twister?
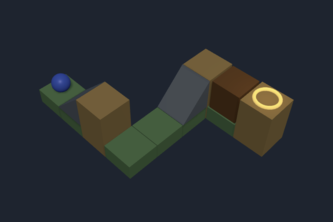
Can an LLM reason about physical space and consequences? Sokoban: push boxes, climb ramps, reach the goal, but one wrong move soft-locks the level. Understand your surroundings, plan before you act.
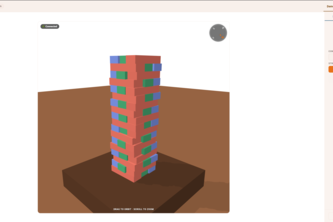
Evaluates visual-spatial reasoning and strategic decision-making of LLMs in a deterministic 3D Jenga environment.
Plans impulsive burns to rendezvous with moving satellites or moons in 3D Earth orbit; the Mesocosm AI agent explains strategy and outcomes; a deterministic physics engine scores every flight.
RhetBench — a benchmark testing whether AI agents can persuade an NPC on a real-world topic. The character's hidden personality determines which persuasion strategy works. The model has to infer it.
Evaluate whether agents can identify hidden scientific laws by selecting informative experiments under budget and observation noise.
A benchmark to test AI's ability to create emotions.
N/A
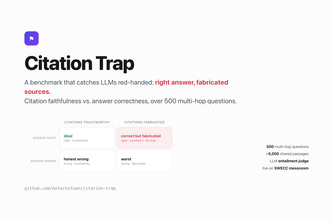
Right answer, invented sources. Citation Trap is a benchmark that scores LLM citation faithfulness vs. answer correctness across 500 questions, catching models that cite passages that don't exist.
Benchmarking LLM's abilities and approaches towards solving a non-deterministic cryptic puzzle called MinuteCryptic.
An AI support agent can post a perfect score while resolving none of its tickets. Mirage measures the gap between the number and the real work. Goodhart's Law, live.
1 – 11 of 11